
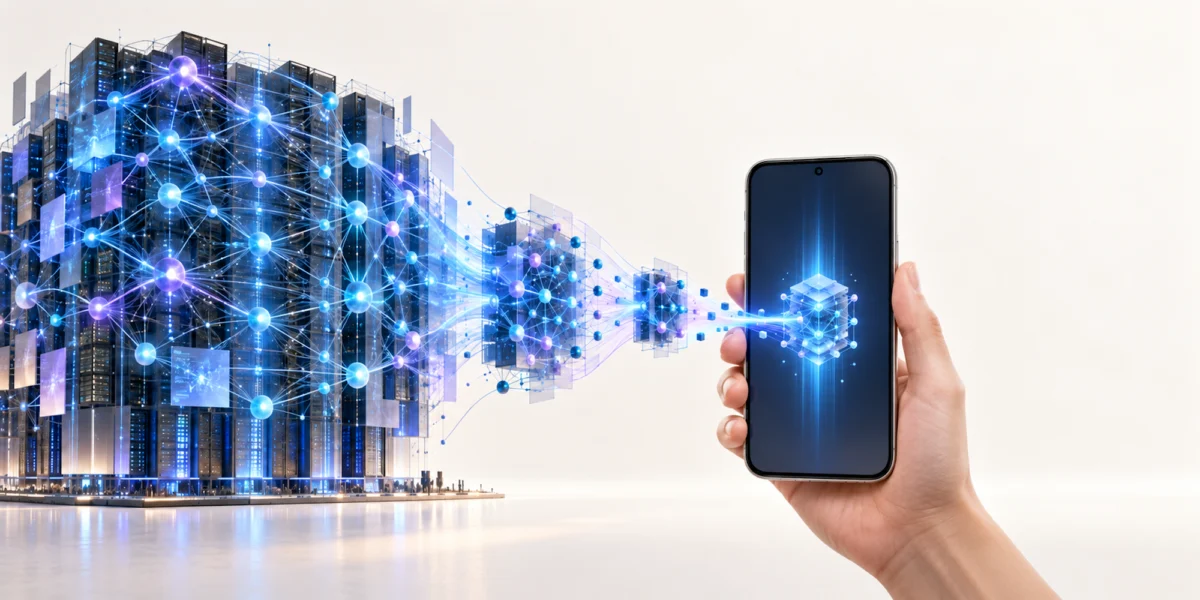
The landscape of artificial intelligence is currently defined by a persistent trade-off: the pursuit of superior reasoning capabilities typically requires massive, power-hungry models that reside in the cloud. However, a California-based startup, PrismML, is challenging this paradigm by demonstrating that high-performance, intelligent models do not necessarily need to be large. By leveraging advanced compression techniques, the company is successfully shrinking sophisticated models to a footprint that fits comfortably on consumer-grade hardware, including personal computers and high-end smartphones.
This shift toward "edge-native" AI—models that execute locally on a device rather than on remote servers—represents a fundamental change in how users interact with machine learning. While PrismML has currently raised a modest $22.25 million in seed funding, the industry is paying close attention, with reports suggesting interest from major technology firms like Apple. Although CEO Babak Hassibi has declined to confirm specific corporate partnerships, the technical trajectory of the firm suggests a pivotal moment in the democratization of generative AI.
The Technical Breakthrough: Ternary Weight Compression
The core of PrismML’s innovation lies in its approach to model weights, which serve as the internal data structures representing the "knowledge" a model acquires during training. In a standard Large Language Model (LLM), these weights are typically stored in 16-bit floating-point format, consuming significant memory. PrismML has pioneered a method known as "ternary" weights.
In this architecture, the model’s weights are compressed into a ternary system, meaning each weight is assigned one of only three values: +1, -1, or 0. This simplification drastically reduces the memory footprint of the model, enabling a 9x to 10x reduction in size compared to the original, uncompressed versions.
The practical application of this research was demonstrated on Thursday with the release of Bonsai 2 27B. This model is a compressed version of Alibaba’s open-source Qwen3.8 27B, reduced to a file size of just 5.9 GB. For context, a model of this caliber would typically require massive VRAM capacity on a dedicated GPU cluster. By compressing it into a sub-6 GB package, PrismML makes it feasible for a standard laptop to run a sophisticated reasoning engine without relying on external internet connectivity.
A Brief History of the Startup and Its Origins
PrismML emerged from the academic environment of the California Institute of Technology (Caltech). Founded by a team of researchers specializing in signal processing and compression, the startup is led by Professor Babak Hassibi, a prominent figure in the field of data compression technology. The company’s pedigree is further bolstered by the involvement of Ion Stoica, a co-founder of data powerhouse Databricks and director of the Berkeley Sky Computing Lab.
The startup’s lineage links it to a broader ecosystem of innovation. The Berkeley Sky Computing Lab has historically been a hotbed for transformative technologies, spawning successful ventures such as Letta and the SGLang project. This institutional backing has provided PrismML with a strategic foundation, helping it secure support from major venture capital entities including Khosla Ventures, Cerberus Capital, and Caltech’s internal investment arm.
The development timeline of PrismML has been rapid. The first iteration of the Bonsai model was released in March of this year. Since that initial launch, the company reports that the original model has surpassed 11 million downloads, with smaller variants accounting for an additional 2.6 million downloads. This widespread adoption in the open-source community provides the startup with a significant feedback loop, allowing the engineering team to iterate on their compression algorithms based on real-world usage data.
Bridging the Gap: Performance Parity
A central concern in model compression is the inevitable loss of "intelligence" or accuracy that occurs when data is simplified. Historically, aggressive compression has led to significant degradation in benchmark scores. PrismML, however, claims to have minimized this effect to a negligible level.
According to internal benchmarks, the Bonsai 2 model achieves 98% of the performance of the original, uncompressed Qwen 27B model. This is a notable improvement over the first version of Bonsai, which hit 95% parity just a few months prior. While Hassibi acknowledges that achieving 100% parity remains a challenge, he argues that the difference is often academic.
In practical, real-world applications, the variance in accuracy is frequently imperceptible. Furthermore, research increasingly suggests that the "harness"—the software environment and prompt engineering framework within which the model operates—is often more critical to output quality than the raw model weights themselves. By optimizing the model to run locally, users can also benefit from lower latency and enhanced privacy, as no data needs to be transmitted to the cloud for processing.
The Strategic Shift Toward Larger Architectures
Looking ahead, PrismML is setting its sights on a new frontier: the compression of multi-hundred-billion-parameter models. As models grow in scale, the sheer volume of redundant data increases, which, paradoxically, may make them easier to compress without sacrificing overall intelligence.
"The next models that we will release, hopefully in the next couple of months, will be in the several-hundred-billion-parameter range," Hassibi explained. "As a general trend, for larger models, it is easier to get to 100% performance parity."
This strategy aligns with the broader industry goal of achieving "intelligence at the fingertips." If successful, the ability to run massive models on consumer devices would effectively bypass the massive compute costs currently associated with cloud-based inference.
Broader Implications for the AI Economy
The implications of PrismML’s work extend well beyond simple hardware efficiency. If high-performance models can run locally and privately, the business model for AI services may undergo a radical shift.
- Privacy and Security: By eliminating the need to send proprietary or personal data to a remote server, local inference models solve the primary obstacle to the adoption of AI in healthcare, legal, and financial sectors.
- Cost Democratization: Running models on existing hardware (PC, smartphone, or local workstation) significantly lowers the cost of deployment. Ion Stoica emphasizes this, noting that because the user has already paid for the hardware, the cost of running the model becomes essentially zero.
- Reduced Dependency on Cloud Infrastructure: While the training phase of AI will likely remain in the cloud due to the massive computational requirements, the inference phase—the actual use of the model—could move entirely to the edge. This would reduce the reliance on centralized GPU-as-a-service providers.
Competitive Landscape and Market Context
PrismML is not working in a vacuum. The field of model compression has seen significant activity as companies race to make AI more accessible. For instance, Multiverse Computing, an outfit founded by researchers from Spain’s Donostia International Physics Center, has similarly invested heavily in compression technology and has secured significant capital to pursue these goals.
The existence of multiple players in this space indicates that the industry views "edge-AI" as the next major growth phase. While some competitors focus on broader quantum-inspired optimization, PrismML has carved out a niche by focusing on ternary weight simplification and demonstrating high-volume adoption via its GitHub-based releases.
As the industry matures, the debate will likely shift from "who has the largest model" to "who can run the smartest model on the smallest device." If PrismML’s trajectory continues, the company may find itself at the center of this shift, effectively rewriting the hardware requirements for modern artificial intelligence. Whether the firm eventually secures a high-profile acquisition or establishes itself as a foundational platform for edge-based LLMs remains to be seen, but its rapid adoption and technical progress suggest a significant disruption in the making.
Conclusion
PrismML’s progress serves as a testament to the fact that optimization is as important as raw power in the evolution of AI. By focusing on ternary weights and the local execution of large models, the company is addressing the most pressing constraints of modern AI deployment: size, privacy, and cost. As the company moves toward compressing even larger models, the gap between what is possible on a central server and what is possible on a user’s pocket device continues to narrow, potentially changing the computing landscape for years to come.




Leave a Reply